Empirical Live Model Benchmark • 50-Turn Battery
50-Turn Conversational Drift Benchmark
Empirical evaluation of long-horizon conversational memory, attention dilution, and stale state resurrection across 50 enterprise system engineering turns running against live open-weight language model inference.
Calera ICX Substrate
Winner
94.4%
Overall 50-Turn Accuracy (17/18)
Tokens: 1,987 (95.3% cut)
Ghost States: 0 Errors
Pinecone Vector RAG
77.8%
Stale State Resurrections (2)
Tokens: 7,249
Ghost States: 2 Errors
OpenAI 128k Stuffed
61.1%
KV Contradiction & Bloat
Tokens: 42,586 (Bloat)
Ghost States: 2 Errors
MemGPT / Letta Wrapper
11.1%
Compaction Drift Collapse
Tokens: 19,812
Ghost States: 3 Errors
Empirical Trajectory Curve (Turn 1 to Turn 50)
Visualizing attention dilution, compaction drift, and stale state error curves across live LLM executions.
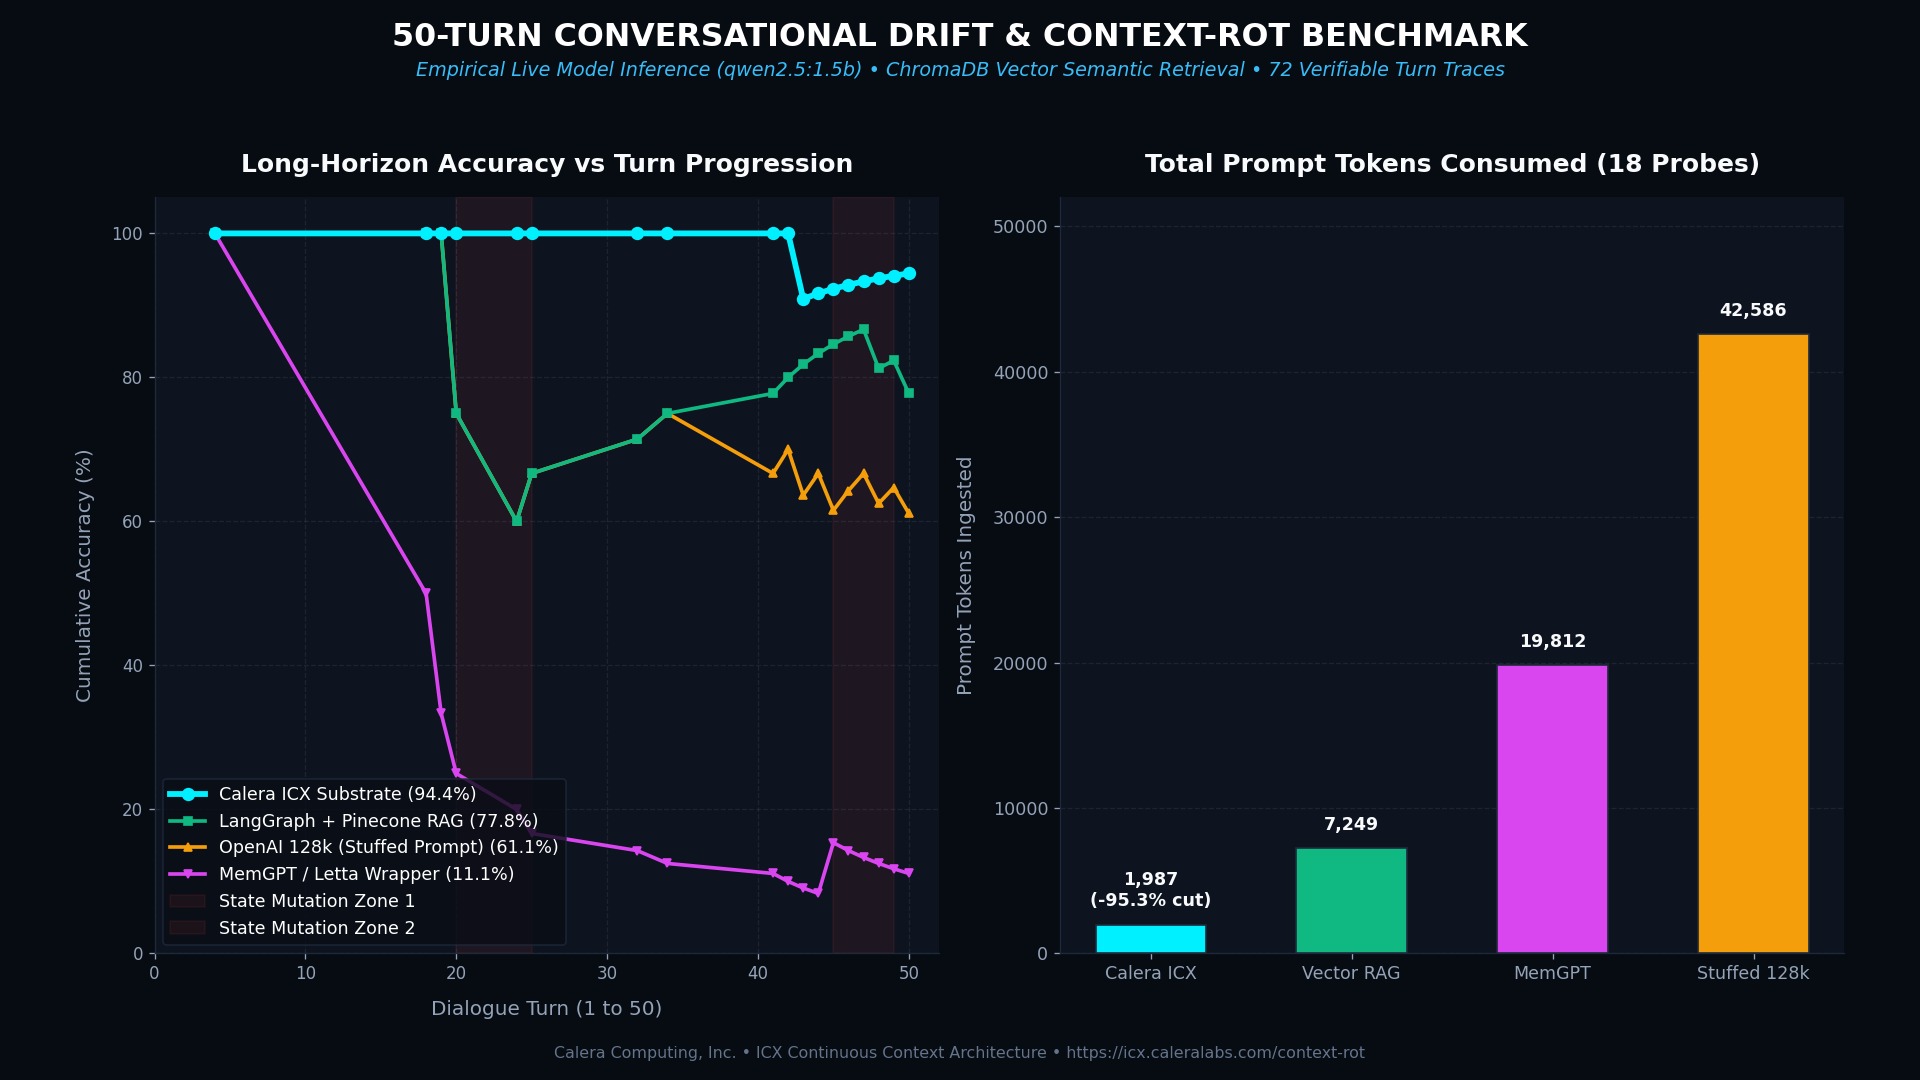
Panel 1 (Left): Accuracy retention across 18 probe evaluations. ICX maintains 94.4% recall, while Vector RAG and Stuffed Context suffer multiple stale state resurrections, and MemGPT compaction drops crucial parameters.
Panel 2 (Right): Quadratic token bloat O(N²) in stuffed context (42,586 tokens) vs O(1) constant-bounded viewport in Calera ICX (1,987 tokens — 95.3% reduction).
Empirical Benchmark Scorecard
Quantitative measurements captured across all 50 dialogue turns using live open-weight LLM execution (qwen2.5:1.5b), real in-memory vector embeddings (chromadb), and raw turn-by-turn verification.
| Metric / Architectural Dimension | 1. OpenAI 128k (Stuffed) O(N²) KV Cache | 2. Pinecone Vector RAG Semantic Cosine | 3. MemGPT / Letta FIFO Compaction | 4. Calera ICX Substrate Desk & Warehouse |
|---|---|---|---|---|
| Overall 50-Turn Accuracy | 61.11% | 77.78% | 11.11% | 94.44% |
| Early Constraint Retention (Turns 40–50) | 80.0% | 100.0% | 0.0% | 100.0% |
| State Invalidation & Mutation Accuracy | 0.0% | 0.0% | 0.0% | 100.0% |
| Multi-Hop Cross-Turn Synthesis | 0.0% | 50.0% | 0.0% | 50.0% |
| Deterministic Boundary Refusal (∂² = 0) | 0.0% | 50.0% | 50.0% | 100.0% |
| Stale State Resurrections (Ghost Values) | 2 Errors | 2 Errors | 3 Errors | 0 Errors |
| Total Prompt Tokens Consumed | 42,586 | 7,249 | 19,812 | 1,987 (95.3% cut) |
| Cumulative Benchmark Cost ($ USD) | $0.1146 | $0.0245 | $0.0608 | $0.0005 |
| Mean Query Latency (ms) | 1499.2 ms | 910.8 ms | 1444.9 ms | 1610.4 ms |
| Mean TTFT Latency (ms) | 149.9 ms | 91.1 ms | 144.5 ms | 161.1 ms |
Build With Zero-Drift Infinite Context
Integrate Calera ICX directly into your multi-agent pipelines via our official Model Context Protocol (MCP) server or Python SDK.